For site authors
You own the words. We own the plumbing.
If you can edit a page and merge a branch, you can run a production website here. There is no cache policy to design, no certificate to renew, and no cloud console to log into. Plain HTML, CSS, JavaScript, and images are enough.
The whole job, four steps
- Repository Already created for you, named the hostname visitors type.
- Two secrets An upload identity and your project prefix. Set once.
- Merge The default branch is production. Listed branches become environment hosts.
- Green check The run ends when the public page returns 200 and its body checksum matches the staged file, not when upload finishes.
That last step is the one people notice. A deploy that “succeeded” while the edge still served yesterday is not a success, so the job sweeps the real durable URLs and confirms their staged and fetched SHA-1 values agree. Dropped durable paths must return 404.
Your hostnames
Production is always the repository name — that 1:1 mapping is what makes the rest safe to automate. Extra environments are branch names, and the hostname is derived for you:
| Kind of site | Production | Environment host |
|---|---|---|
| Zone apex | example.tld | preview.example.tld (the only extra name accepted) |
| Label site | www.example.tld | www-preview.example.tld (leftmost label gets the dash) |
The dash is not decoration. It keeps a label site from quietly taking preview.example.tld, which belongs to whoever is authorized for the zone apex. Deploy and purge both fail closed if a run names a hostname that is not its own.
What happens to your files
By default we hash everything except HTML index pages and any paths you explicitly list. A stylesheet becomes something like site-1f4e79ab-20260830.css — content hash plus the deploy date — and your HTML is rewritten to point at it. The platform’s version.txt lives under sibling state/, outside the tenant hostname's visitor route.
Because those URLs change whenever the bytes change, browsers can hold them for 30 days as immutable. Your entry pages take the opposite deal: browsers must revalidate them every time, so a visitor never keeps HTML that points at assets we have already replaced.
Already using a generator that fingerprints its own output? Passthrough mode skips our renaming and classifies by filename instead.
Pages at a stable URL are expensive: we purge them from the edge on every single deploy, and a purge request carries at most 100 path expressions. Keep that set small. If the durable union grows larger, the platform rolls the deepest, smallest overlapping directory groups into covering wildcards before falling back to /*. It covers the complete set in one purge rather than delaying objects beyond 100 to a second run. If you need a durable /about.html instead of a fingerprinted one, add it deliberately.
Previews without a second anything
A preview host is the same repository, the same two secrets, and the same storage prefix — just another branch. Stakeholders get a URL instead of a zip file. Worth knowing: each hostname is its own cache at the edge, so publishing to production does not refresh preview, and vice versa.
Optional: shrink your images
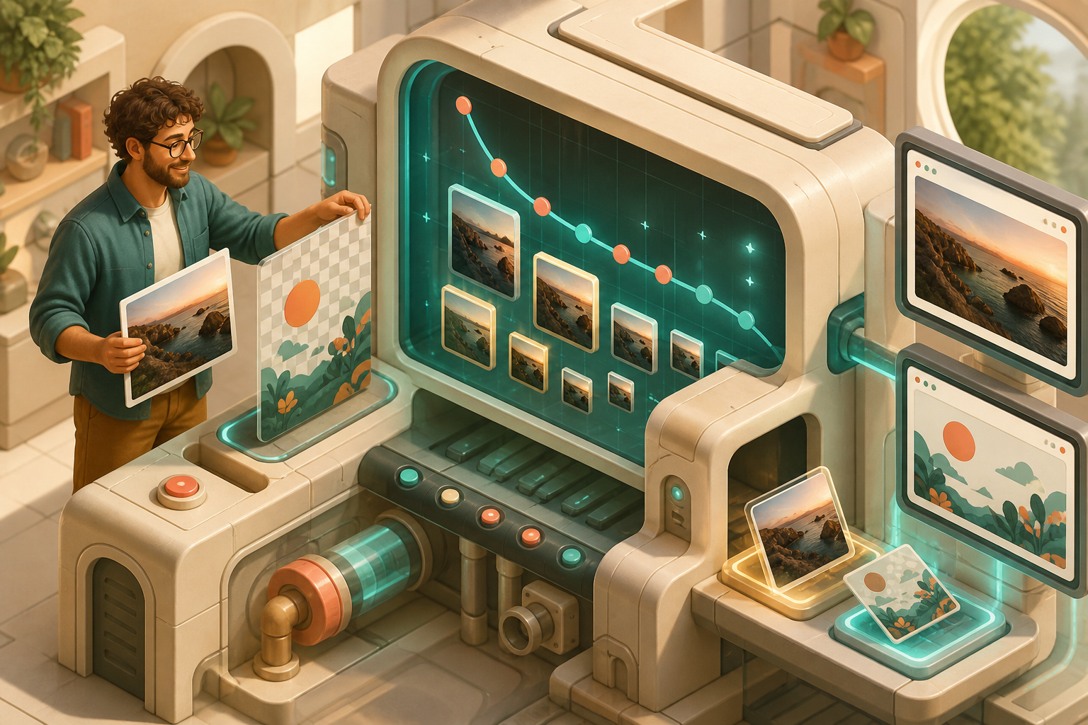
Hosting does not care how large your photos are, but your visitors do. This site’s repository carries a local compressor that derives the real display widths from the page layout, evaluates each format on perceptual quality and byte size, and keeps the best encoding for each width. Every derivative name includes a short effective source identity: the untouched original’s SHA-1, plus reviewed crop coordinates when a coordinate-named preview exists. Matching source, crop, and output digests reuse the existing set without another search; changing an input creates a new set and removes the old local files. The script writes a JPEG or PNG fallback into responsive HTML; the site’s loader substitutes AVIF or WebP only when that exact modern candidate won and the browser can decode it.
Questions we actually get
Do I need a cloud account?
No. Publishing happens through the repository’s workflow using a federated identity. Authors do not receive storage keys, and direct access to the storage account stays with platform engineering.
Can I change cache headers?
They are inputs, so technically yes — but they are the safety rails. Getting them wrong can pin visitors to stale HTML that references deleted assets, skip the purge entirely, or overflow the 100-path purge limit. Leave them off your workflow unless you have read the cache post.
Can I add a second website to my repository?
No. A second public hostname is a second repository with its own prefix and identity. Environment hosts are only alternate branches of the same site.
Can I clear the whole site cache?
Yes. Run the repository’s manual Purge all workflow and type one of your provisioned FQDNs. It durably queues /*, asks the platform to purge, verifies current durable origin objects through that hostname, and clears the queue only after success.
Who fixes DNS and certificates?
Not you, and not from your workflow. Certificates are managed and automatic. DNS is either ours to write or a short record sheet handed to whoever runs that zone.
Deeper reading: onboarding, fingerprinting, cache, the image optimizer. Or see the pipeline diagrams.